The mtk_soc_eth driver on the Beryl AX (GL-MT3000) with firmware 4.9.0 falsely advertises TSO/GSO capability (NETIF_F_TSO) for its LAN interface. This causes the kernel to send large GSO frames (e.g., tcp.len > 15000) to the NIC. The hardware or its firmware fails to segment these frames, resulting in corrupted or oversized packets being sent over the LAN. This leads to TLS decryption failures (SEC_E_DECRYPT_FAILURE) on downstream clients, especially when using USB hubs with Ethernet ports.
The issue is not with downstream devices, but with the driver's lack of a software segmentation fallback. The driver promises hardware segmentation but fails to deliver, breaking the TSO contract.
Workaround:
- Disable GSO/TSO on the LAN interface:
ethtool -K eth1 tso off gso off
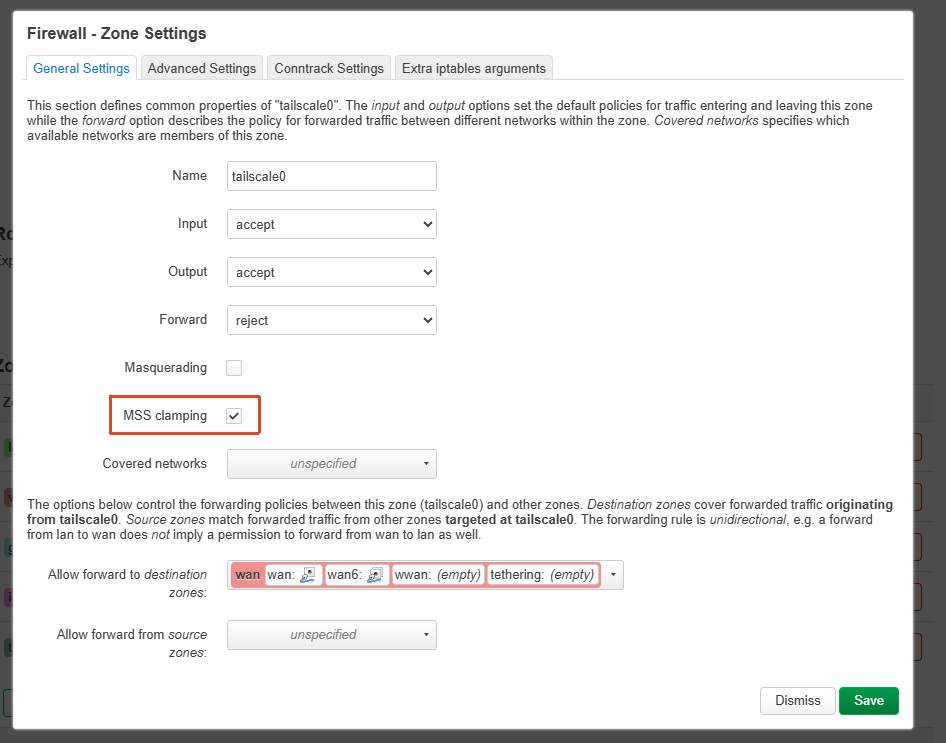
- Add persistent MSS clamping:
iptables -t mangle -A FORWARD -o tailscale0 -p tcp --tcp-flags SYN,RST SYN -j TCPMSS --clamp-mss-to-pmtu in /etc/firewall.user
Impact:
Large HTTPS downloads fail intermittently. The issue does not affect Wi-Fi, as its driver handles segmentation correctly.
Please fix the mtk_soc_eth driver to either provide a software fallback or not advertise TSO/GSO if the hardware cannot reliably perform segmentation.
1 Like
Hi,
Sorry for the delayed reply.
And thank you as well for your report.
Could you please help clarify the following so that we can investigate the issue further?
- Which feature is this issue related to? Based on the iptables rule you provided, it seems to be related to Tailscale.
- What exactly happens when the issue occurs? For example, when accessing a HTTPS service on remote Tailscale node, do LAN clients experience TLS decryption failures, with packet captures showing Ethernet frames/TCP packets larger than 15000 bytes?
What seems a bit strange is that MSS clamping should already be enabled by default for the tailscale0 zone.
- Yes, the setup was using Tailscale subnet routing via an exit node.
- Correct, the router sends oversized packets downstream and LAN clients experience eventual
SEC_E_DECRYPT_FAILURE.
I can confirm that MSS clamping also appeared to be enabled by default according to LuCI but in the end this turned out to be misleading and unreliable. Turning off GSO/TSO drastically reduced the frequency of TLS connection failures, however it did not completely eliminate the issue. After both having the former workaround in place and enforcing MSS clamping via the iptables rule, I observed no further failures.
I’ve done some more testing and think I’ve isolated the cause. TSO itself was not necessarily at fault, but rather the TX checksum logic it relies upon. The hardware/driver checksum implementation calculates incorrect checksums for large packets, hence the silent data corruption leading to SEC_E_DECRYPT_FAILURE on TLS streams.
The more precise workaround is to simply disable TX: ethtool -K eth1 tx off
This will also implicitly disable TSO since it requires TX to function. It seems to resolve the corruption by forcing accurate calculation by the CPU, while leaving GSO intact.
The driver apparently still needs a fix for the hardware checksum logic to get things working as they should be.
Thank you for the clarification and the additional information.
We will ask the development team to investigate further and determine how to address the issue, if it is confirmed to be a bug.
Hi
We have performed some testing locally, but unfortunately we have been unable to reproduce the issue.
Could you please follow the guide and share your device with us via GoodCloud so that we can investigate it remotely?
(If possible, please also provide the specific steps to reproduce the issue.)
Kindly send us the router's MAC address and password via private message so that we can access the device.
Sent further details via DM.
Any update on plans to fix this bug?
Thank you for following up.
We previously tested this internally using the steps provided, but were unable to reproduce the issue on the Beryl AX.
More recently, another user reported a potentially similar issue on the same MediaTek-based Flint 2 (GL-MT6000). We have reproduced that issue internally and are investigating whether the two reports share the same root cause, as well as a possible fix. We cannot yet confirm that they are the same issue.
We will share any relevant updates here when available.